Cutting the memory LLMs need, so they can run on-device.
Hello! I’m Lee DongWon, a Software Convergence undergraduate at Kyung Hee University and an undergraduate researcher at the EMIL Lab, advised by Professor Sungha Choi. I study KV cache quantization to cut LLM memory for on-device inference, aiming for work that reaches real products. I also love AI tools and heavily use agentic AI like Grok Bot.
Projects, each explained in about 20 seconds
Long-video understanding in a third of the KV memory
Capstone, Jun. 2026 to present
INT4 storage for the kept KV cache on top of InfiniPot-V, with Qwen2-VL-7B. About a third of the KV bytes at the same 6K budget, accuracy on par with FP16.
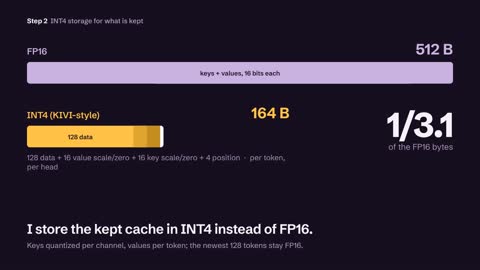 Long-video understanding in a third of the KV memoryIn progress
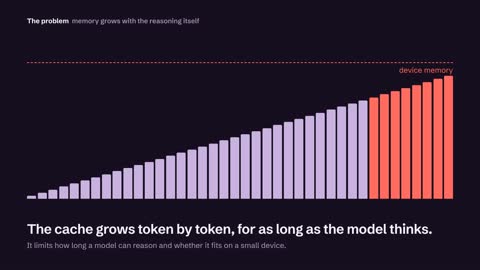 KV cache quantization for reasoning LLMsIn progress
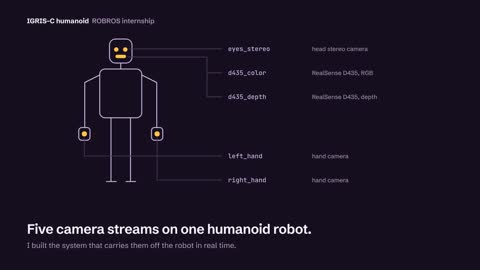 Real-time camera streaming for a humanoid robotROBROS, Dec. 2025 to Mar. 2026
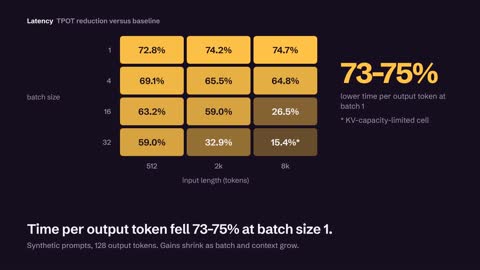 LLM inference optimization on DGX SparkSpeculative decoding with vLLM
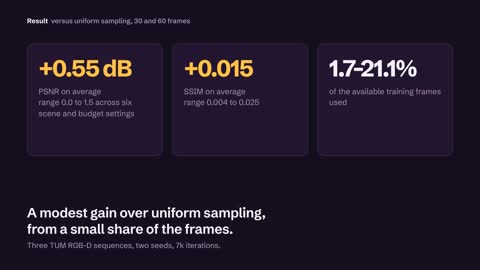 Keyframe selection for 3D Gaussian SplattingTUM RGB-D, gsplat
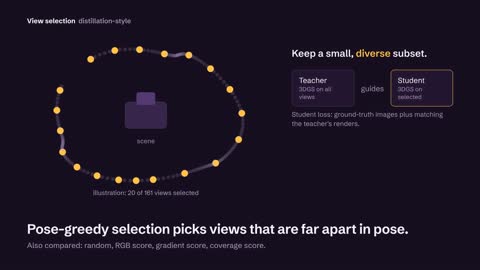 View selection for data-efficient 3D reconstructionMar. to Jun. 2026
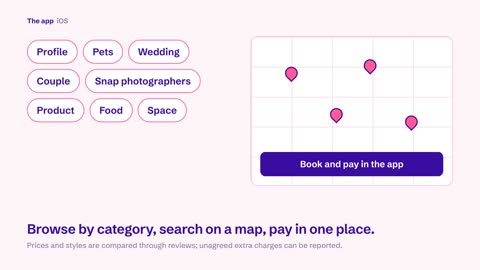 찰칵의 덕후: photo studio and photographer finder appStartup, Mar. 2024 to Jul. 2025
Also ongoing since Mar. 2025: GPU-accelerated LLM inference, covering GPU kernel optimization and self-hosted LLM serving with vLLM on limited GPU resources.
Experience
-
Undergraduate Research Intern
EMIL Lab, Kyung Hee University
- Evaluated an initial KV cache quantization approach for long-context LLM reasoning; a modified ThinKV implementation showed a 47.5 percentage-point accuracy gap versus FP16 on an AIME 2025 subset (10 problems × 4 responses, DeepSeek-R1-Distill-Qwen-14B).
- Redirected research to importance-based global KV cache quantization, targeting lower memory use while preserving reasoning accuracy.
-

Robotics System Software Engineer Intern
ROBROS, Seoul, South Korea
Built and tested a humanoid SLAM image-streaming module on edge devices (Jetson Orin Nano, Intel NUC) over heterogeneous networks, tuning CycloneDDS and Zenoh in C++ and Python.
-
Undergraduate Research Assistant
Kyung Hee University, Yongin, South Korea
- Led end-to-end data analysis for a joint study with social science researchers on ChatGPT as an AI textbook alternative.
- Processed multimodal data, built ML/DL models, and validated findings through empirical analysis.
-
Sergeant
Republic of Korea Army
Completed mandatory military service.